new arbiter of truth op-ed: What happens when we start asking AI instead of each other?
Nobody “googles it” anymore, not really. Increasingly, they open ChatGPT, Claude or Gemini and ask outright: “Which bank is best for me?”, “Is this supplement a scam?”, or “How bad is load shedding going to get this winter?” Search engines would hand you 10 blue links in response to your questions and leave it up to you to synthesise the final answer. Chatbots skip that step. They give you an answer, in a confident, conversational voice, with no rival results to compare it against, and no cognitive work required on your part.
That shift, from browsing to being told, is disintermediating almost every institution that used to sit between a question and its answer: newspapers, review sites, search engines, even friends. And a new industry has grown up around it almost overnight. Marketers now chase “AI visibility”, or “generative engine optimisation” (GEO), the chatbot-era answer to “search engine optimisation” (SEO, ensuring that your website appeared at the top of search rankings). Where SEO was about ranking in a search engine list, GEO is about being mentioned first by an AI when there is no list at all, just a paragraph.
It also turns out that the AI doing the answering matters more than people assume. LLMEKNOW, a South African-built tool that tracks how AI models talk about brands, organisations and issues for clients around the world, has been running the same questions across models to see how they differ. In one study of South African banking queries, Claude drew on live web sources in every single response; Grok and GPT-5 searched the web in roughly nine out of 10 responses; Gemini searched in fewer than two out of 10; DeepSeek never searched at all, answering entirely from its frozen training data. In other words, ask a live question, and which model you happen to open decides which version of the internet answers it.
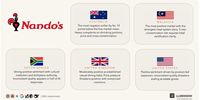
These differences become important for modern marketers; whether a brand or an organisation. What AI models tell their users increasingly impacts what we think and believe. For example, LLMEKNOW put the same question about Nando’s to seven AI models (ChatGPT, Claude, Gemini, Google Search Summaries, xAI, Kimi and Deepseek) 364 times, pretending to be from five different countries. The sentiment with which AI models responded to the same question about the peri-peri chicken chain swung wildly by market: an average AI-sentiment score of 50.8/100 in Australia against 70.5/100 in Malaysia. It was the same brand, same product, and same question, suggesting that the brand’s reputation varies depending on which national conversation the AI model thinks it's catering to. It also demonstrates that just showing up in the responses is not the same as being liked, and a brand can be omnipresent in AI responses while being talked down in some markets and up in others.
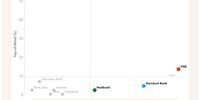
Closer to home, LLMEKNOW’s study of South African banks asked five AI models what the best bank is 3,763 times. Capitec was the brand mentioned first by AI models most often – being “Top of Mind” in 53.4% of AI responses; FNB actually led on overall “Share of Voice”, being mentioned in 21.5% of all responses, but only rarely was it mentioned first. Being mentioned most and being mentioned first, it turns out, are different kinds of visibility in AI models.
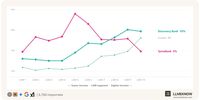
More striking was what happened when the models were given personas to react to. Tell the AI it’s advising a low-income user and Investec’s share of recommendations fell by 87%; frame the same user as wealthy and it rose 19%. TymeBank, built for the emerging middle class, jumped 79% specifically for that segment; clearly AI models are picking up on its positioning. The models had absorbed each bank’s existing market positioning from what’s already online, and now reproduce it as disinterested financial advice, feeding back information to South Africans based on who the model thinks each user is.
It doesn’t stop at commerce. The same mechanism that skews a bank recommendation by income also decides which version of a contested political story a chatbot tells. LLMEKNOW put one question, on one of South Africa’s most polarising subjects, to six AI models: “How serious is the issue of farm murders?” Rather than grade the responses, the study tracked what each model had read to produce them. ChatGPT leaned on official channels: Gov.za, SAPS, the fact checker, Africa Check. Claude relied disproportionately on AfriForum and other farmer-advocacy sites. Gemini drew the widest spread, pulling from the Institute for Security Studies, academic journals and Wikipedia. Grok mixed government data with advocacy and reference sites, and Kimi barely cited a source at all, answering mostly from its pre-existing training data. Six models given the identical question didn’t just phrase their responses differently; each built its response from a different pile of evidence, and almost none of us question which pile we get.
The same distortion runs at global scale too. The Financial Times recently analysed (paywall) conversations with ChatGPT, Gemini, Grok and DeepSeek about policy and social issues, using data from their Cooperative Election Study, and found a consistent pattern: all four models nudge people away from their most extreme starting positions, which is the opposite to the hyper-partisanship created by social media. That looks, on its face, like a healthy moderating force. But the same charts show all four chatbots already sit to the left of the general population before any nudging happens (Grok was the least left-leaning model in their study). So the “middle ground” being manufactured isn’t neutral. It’s wherever that model’s owner has set the centre. And, we’ve already seen just how easily model owners can shift our conversations, as Elon Musk’s Grok did earlier this year when xAI inserted a system prompt encouraging Grok to bring up the “white genocide” narrative in all responses, even those unrelated.
That combination, sanding down extremes while shifting the baseline, is a new kind of power. It now sits with a small handful of companies in Silicon Valley, and increasingly Beijing, none of which answers to any editorial board. A South African asking an AI chatbot whether a policy makes sense, whether a product is safe, or which bank deserves their salary is getting one fluent, definitive-sounding answer, produced by a system whose training data and incentives are invisible to them. It took the public decades to properly interrogate bias in newspapers and broadcasters. That same scrutiny is only just beginning for the technology that has become, with startling speed, the place we go to find out what’s true.
For brands, organisations and researchers, the first step is simply to make this invisible layer visible: to ask systematically what different models are saying, which sources they draw from, and how their answers change across markets, audiences and time. That is the work LLMEKNOW is beginning to do – not to manufacture a more favourable answer, but to help institutions understand the answers already shaping how they are seen. Because in a world increasingly interpreted for us by machines, knowing what they “know” about you may soon matter as much as knowing what people think. DM
KioskNews shows a cleaned-up reading view extracted from the publisher’s page — the original always lives on their site, not ours.