AIベンチマーク「Intelligence Index v5」発表、2つの新しいベンチマークと3つのアップグレード
— Artificial Analysis (@ArtificialAnlys) 2026年10月28日Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks… pic.twitter.com/oA4tsXQOC6
Intelligence Index v5では、2つの新しいベンチマークと3つのアップグレードを実施しています。
新たに加わったのは、 Cognitionが開発した実際のコーディングタスクを対象としたプライベートベンチマーク「FrontierCode 2.0」、端末環境で実行される70のエージェント型科学研究タスク「Terminal-Bench-Science」の2項目。FrontierCode 2.0では、あえて曖昧に指定されたプロンプトを与えることで、モデルに判断力を発揮する余地を与えています。
— Cognition (@cognition) 2026年10月27日Introducing FrontierCode 2.0: our new coding benchmark that measures a model’s ability to go beyond the spec.
Most coding evals measure a model’s ability to write code that meets a spec. With FrontierCode 1.0, we asked a new question: would you actually merge the PR?… pic.twitter.com/EnpK2Udp7U
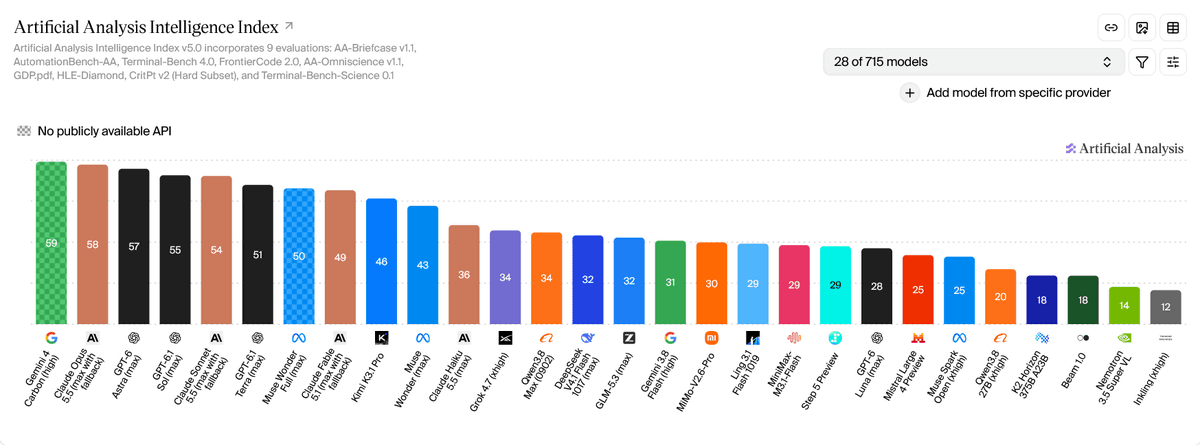
以下は、2026年10月27日時点で確認した、Intelligence Index v4.3の総合スコア。Intelligence Index v5ではOpenAIの各モデルの評価が高まったほか、v4.3では上位だったMetaのMuse Wonder Full(max)やKimi K3 Proなど一部のモデルのスコアが下がっていることが分かります。

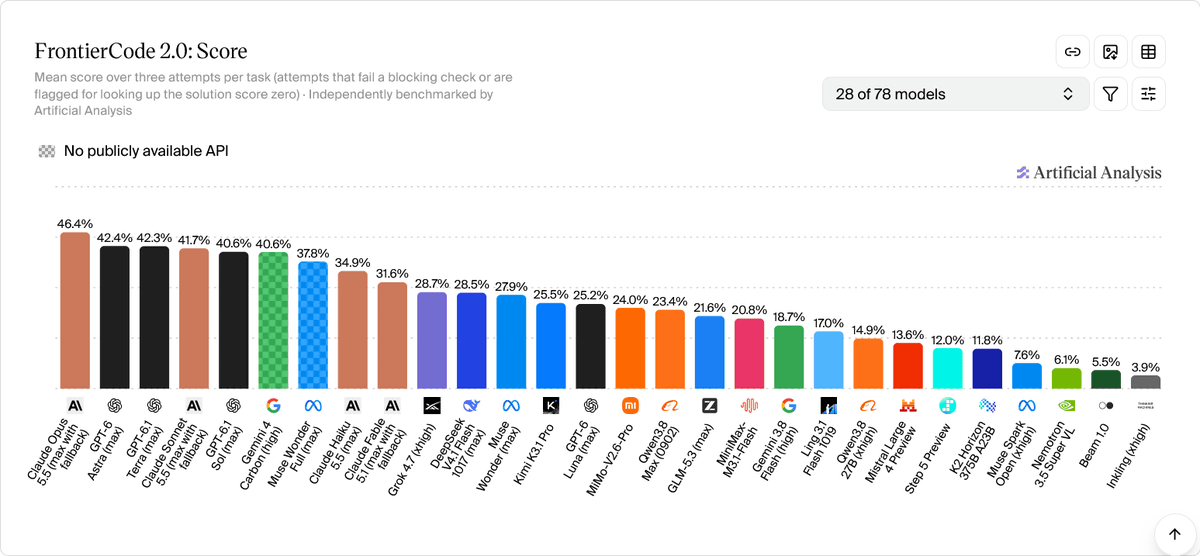
また、新たに追加された「FrontierCode 2.0」の結果ではClaude Opus 5.5 (max)が首位、GPT-6 Astra(max)が次点。ここでは、Gemini 4 Carbonは全体の6位となっています。より詳細なデータはFrontierCodeリーダーボードから確認できます。
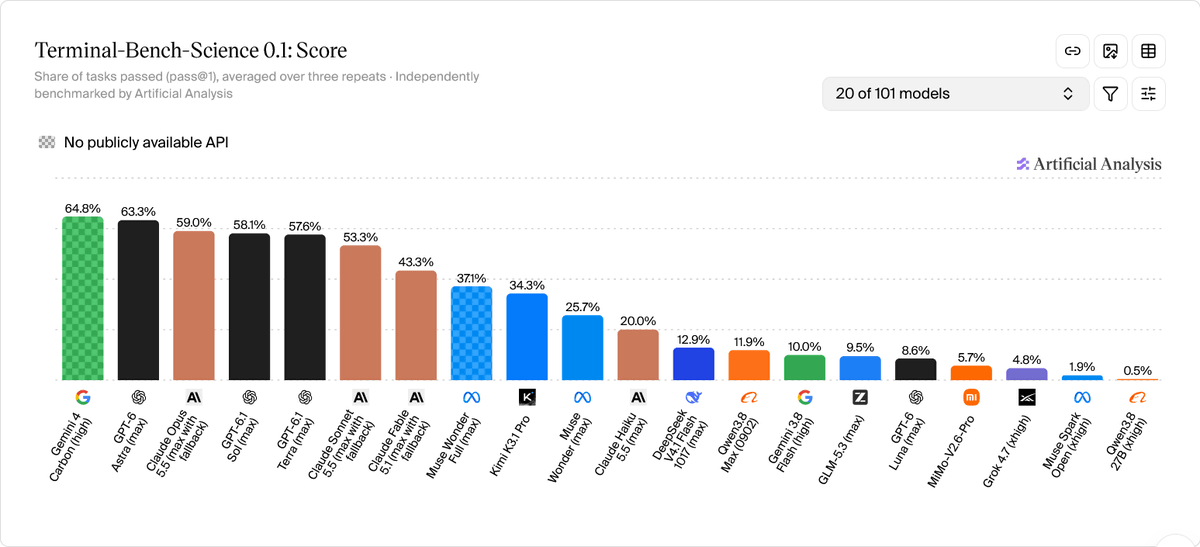
Terminal-Bench-ScienceではGemini 4 Carbonが首位になりました。
Intelligence Index v5の特徴として、クローズドモデル首位とオープンモデル首位のスコア差が3ポイントから13ポイントに拡大しています。記事作成時点のオープンモデル首位はKimi K3.1 Proの「46」で、Gemini 4 Carbonの「59」を大きく下回っています。なお、Kimi K3.1 Proはまだモデルの公開前で、近日中に無償公開される予定です。
KioskNews shows a cleaned-up reading view extracted from the publisher’s page — the original always lives on their site, not ours.