NVIDIAが文字起こしAI「Nemotron 3.5 Transcribe」を公開、大勢が同時に話す場面でも高精度な話者識別が可能
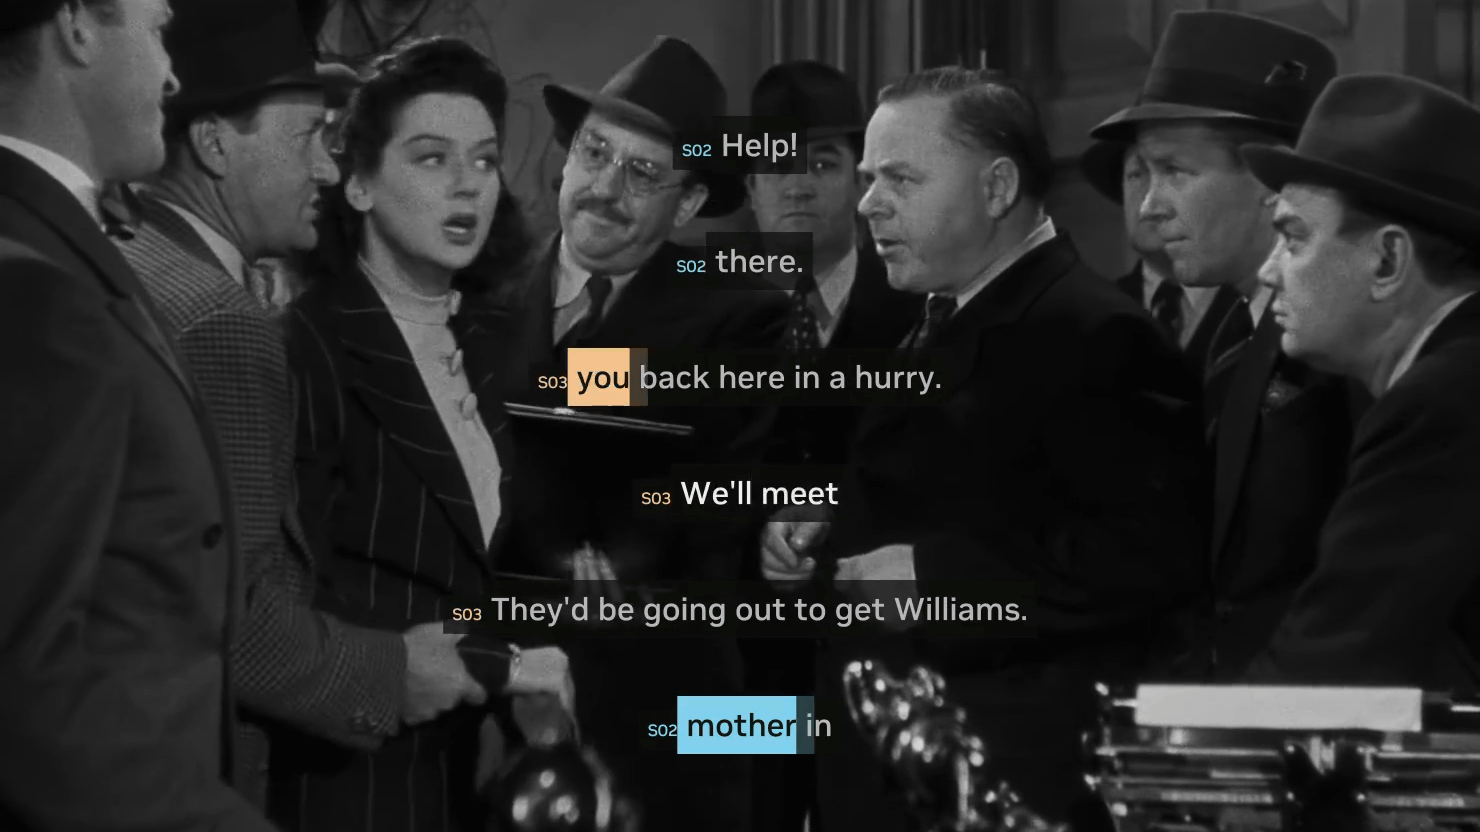
NVIDIAが文字起こしAI「Nemotron 3.5 Transcribe」を現地時間の2026年10月28日に公開しました。複数の話者を識別しながら高精度な文字起こしが可能です。
NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
https://huggingface.co/blog/nvidia/nemotron-transcribe-granary
Nemotron 3.5 Transcribeは総パラメーター数340億・アクティブパラメーター数43億のMoEモデルです。最長1時間の音声ファイルを入力して文字起こし可能で、日本語を含む40言語に対応しています。NVIDIAは言語ごとの文字起こし精度を「Leading(業界最高峰の精度)」「Production-ready(製品化可能な精度)」「Supported(対応はしている)」の3段階に分けており、日本語の精度はProduction-ready(製品化可能な精度)です。
以下の投稿には、1940年に公開された映画「ヒズ・ガール・フライデー」の1シーンを文字起こししたデモ動画が含まれています。複数の人物が早口でまくしたてるシーンでも発話者ごとに分類して正確に文字起こしできていることが分かります。
— NVIDIA AI (@NVIDIAAI) October 28, 2026Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who… pic.twitter.com/PEH1PeURIv
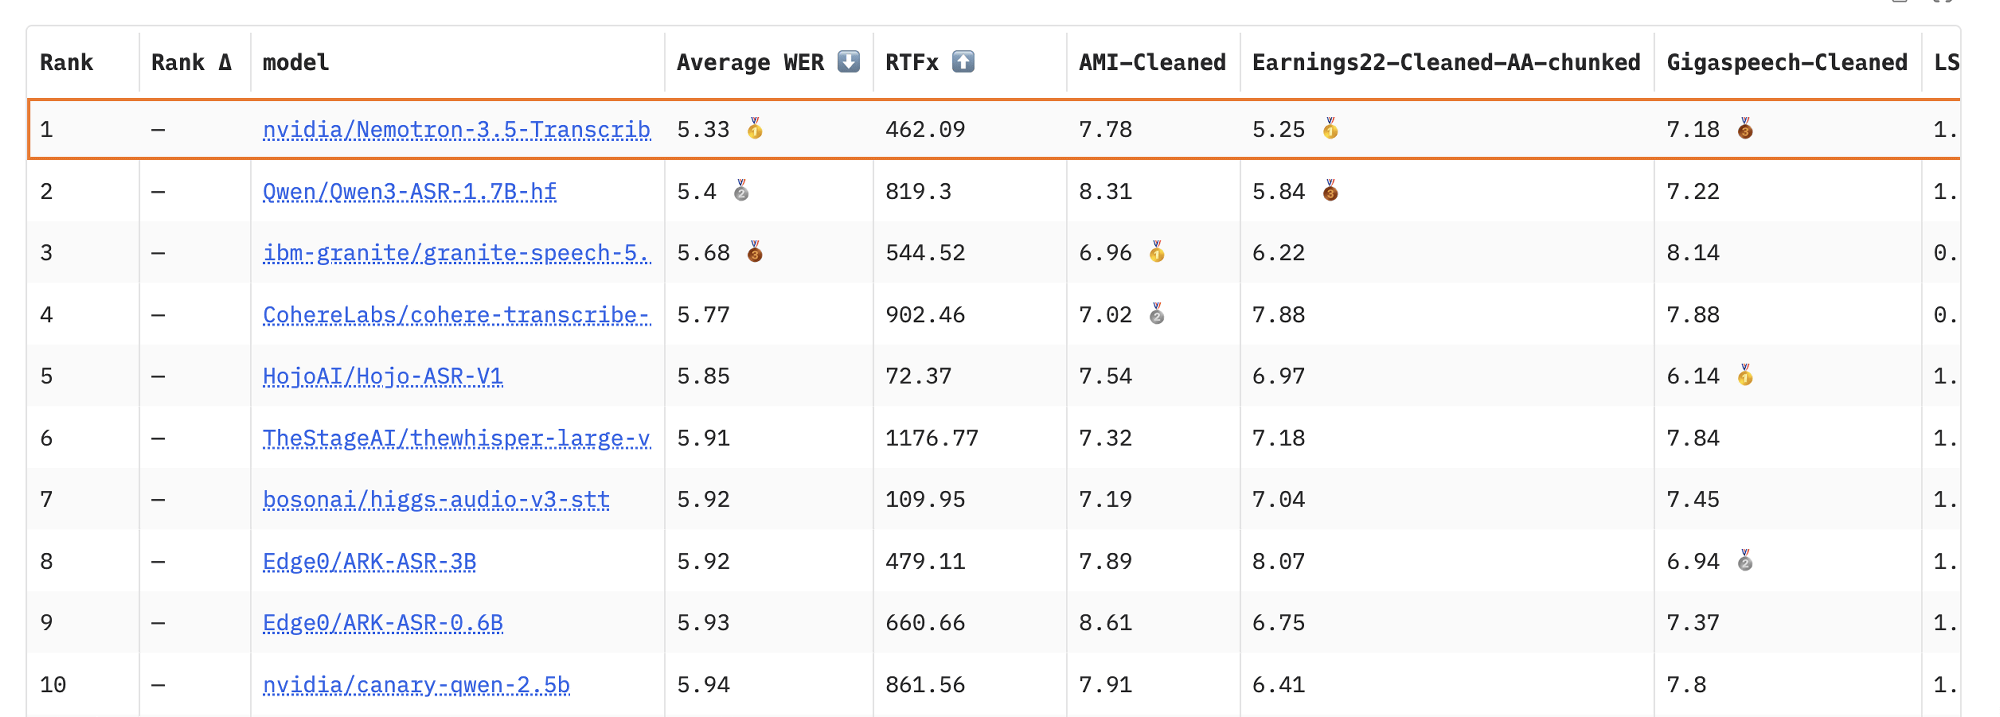
文字起こしAIの性能ランキング「Open ASR Leaderboard 」の英語部門ではNemotron 3.5 Transcribeがオープンモデルの中で最高性能と評価されています。
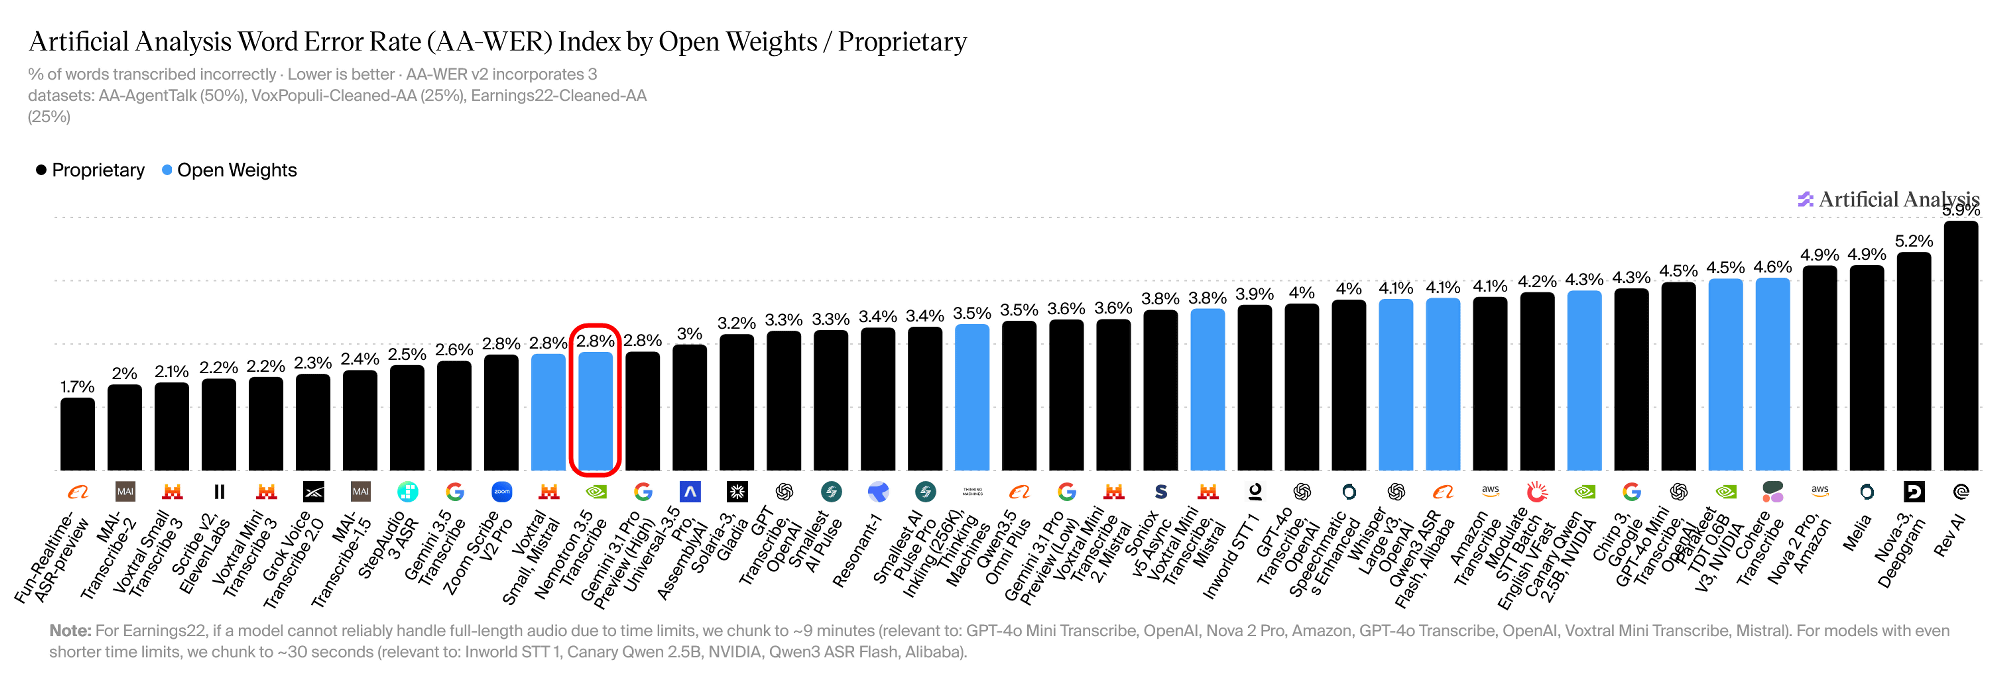
文字起こしのエラー率を測定する「Artificial Analysis Word Error Rate Index (Non-streaming)」でもVoxtral Small Transcribeと並んでオープンモデルの中で最高性能と評価されました。
以下のグラフは横軸がアクティブパラメーター数、縦軸がエラー率を示しています。Nemotron 3.5 Transcribeは同等精度のモデルの中でアクティブパラメーター数が最も少ないモデルであることが分かります。
KioskNews shows a cleaned-up reading view extracted from the publisher’s page — the original always lives on their site, not ours.