NVIDIAが「社内に蓄積した大量の情報をAIで扱えるようにデータ整形して検索可能にするモデル群」を無償公開
NVIDIAが検索拡張生成(RAG)用のAIモデル群「Nemotron Retriever」に5種類のモデルを追加しました。すべてのモデルがオープンモデルとして無償公開されています。
NVIDIA Nemotron 3.5 Embed, Rerank, and Parse: Advancing Agents with World-Class Retrieval Models
https://huggingface.co/blog/nvidia/nemotron-retriever-world-class-agentic-retrieval
公開された5種類のモデルの概要は以下の通り。
Nemotron-3.5-Embed-8B-BF16:日本語を含む34言語に対応した埋め込みモデル。画像とテキスト入力に対応。
Nemotron-3.5-Embed-1B-BF16:Nemotron-3.5-Embed-8B-BF16の小規模版
Nemotron-3.5-Embed-1B-NVFP4:Nemotron-3.5-Embed-1B-BF16のNVFP4量子化版
Nemotron-3.5-Rerank-8B-BF16:クエリと画像およびテキストの関連性ランキングを作成できるモデル
Nemotron-3.5-Parse:PDFファイルの内容をAI処理しやすいデータに整形するモデル
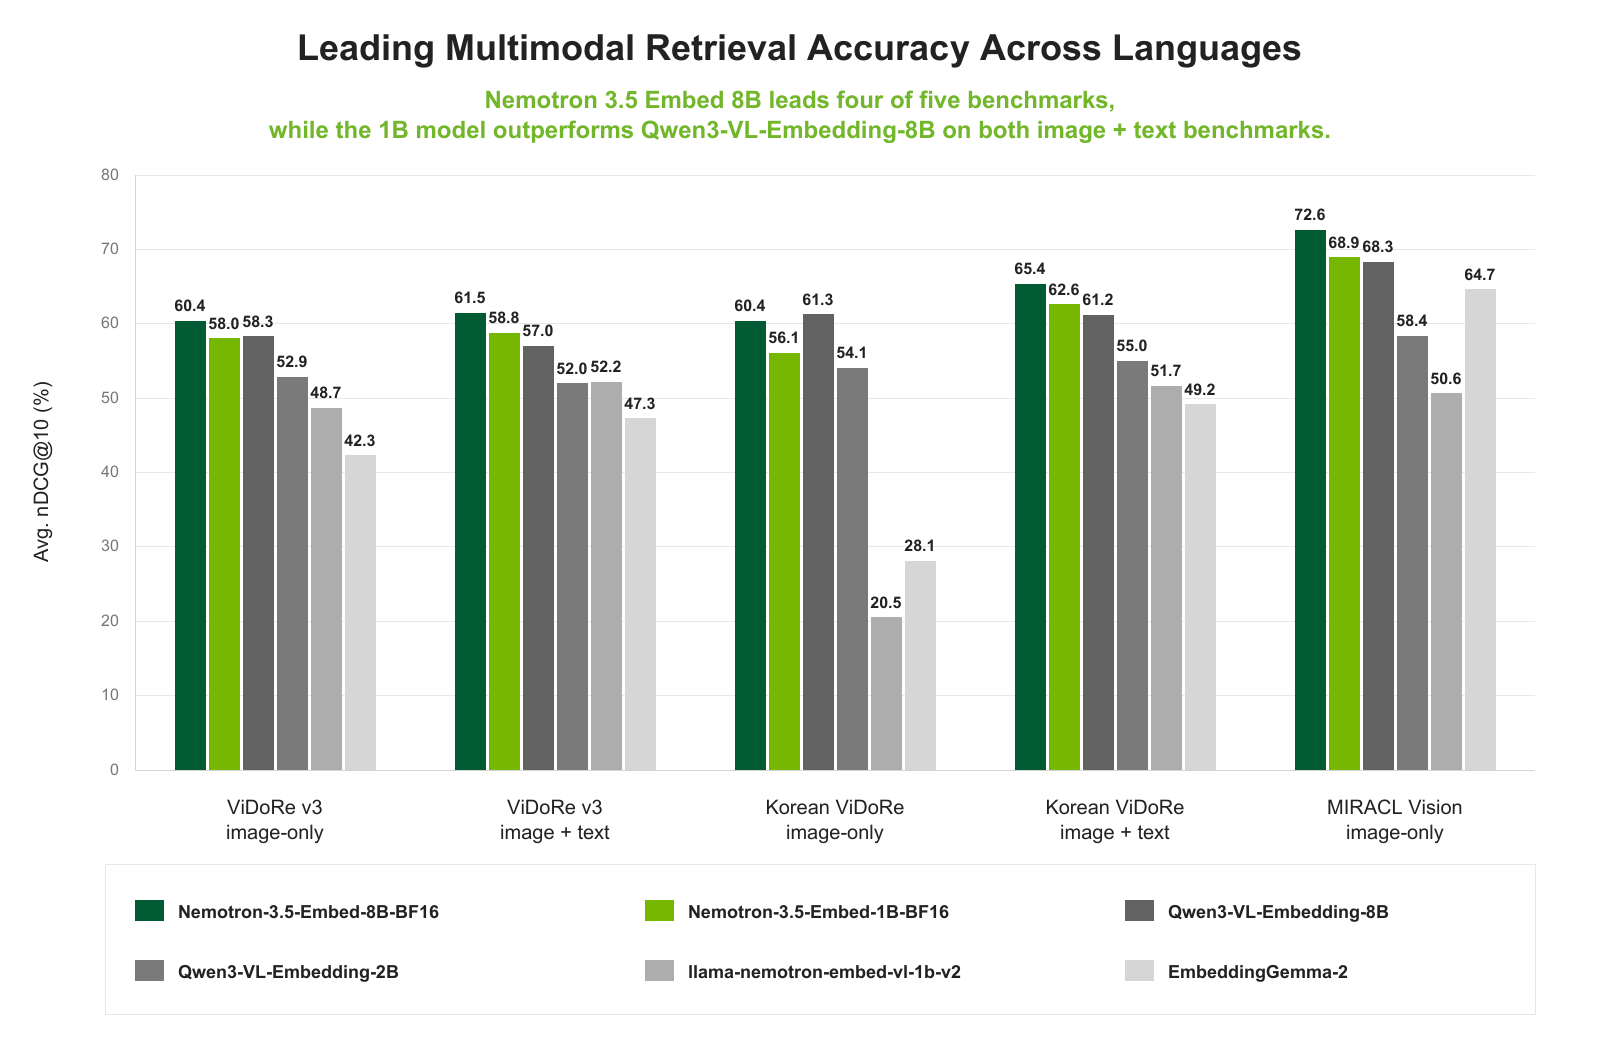
各種埋め込みモデルのベンチマークスコアを並べたグラフが以下。Nemotron-3.5-Embed-8B-BF16はQwen3-VL-Embedding-8BやEmbeddingGemma-2を上回るスコアを記録しています。また、小規模なNemotron-3.5-Embed-1B-BF16もQwen3-VL-Embedding-8Bに近い性能を示しています。
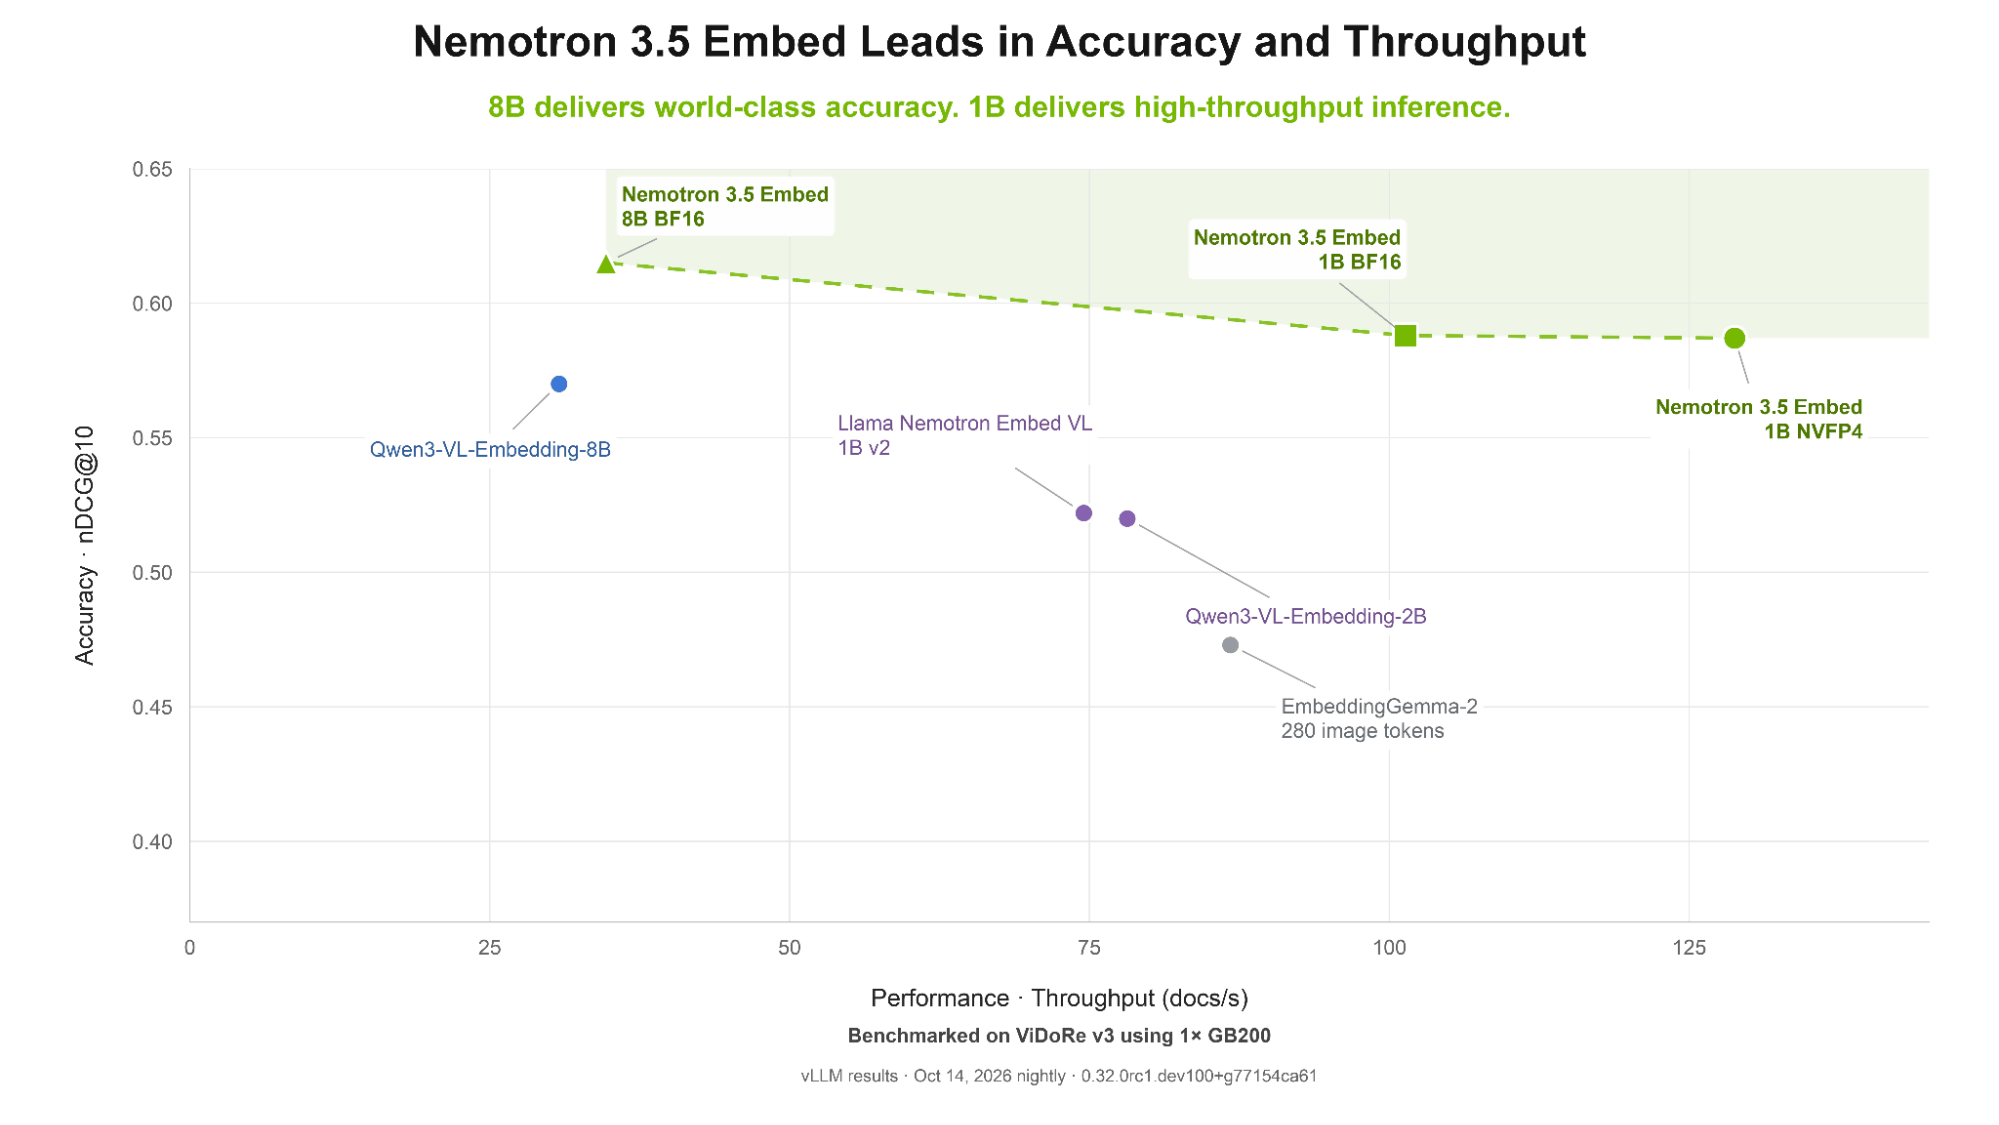
以下のグラフは横軸が処理速度、縦軸が処理精度を示しています。「Nemotron-3.5-Embed-8B-BF16」「Nemotron-3.5-Embed-1B-BF16」「Nemotron-3.5-Embed-1B-NVFP4」の3モデルが競合モデルと比べて高速かつ高精度であることが分かります。
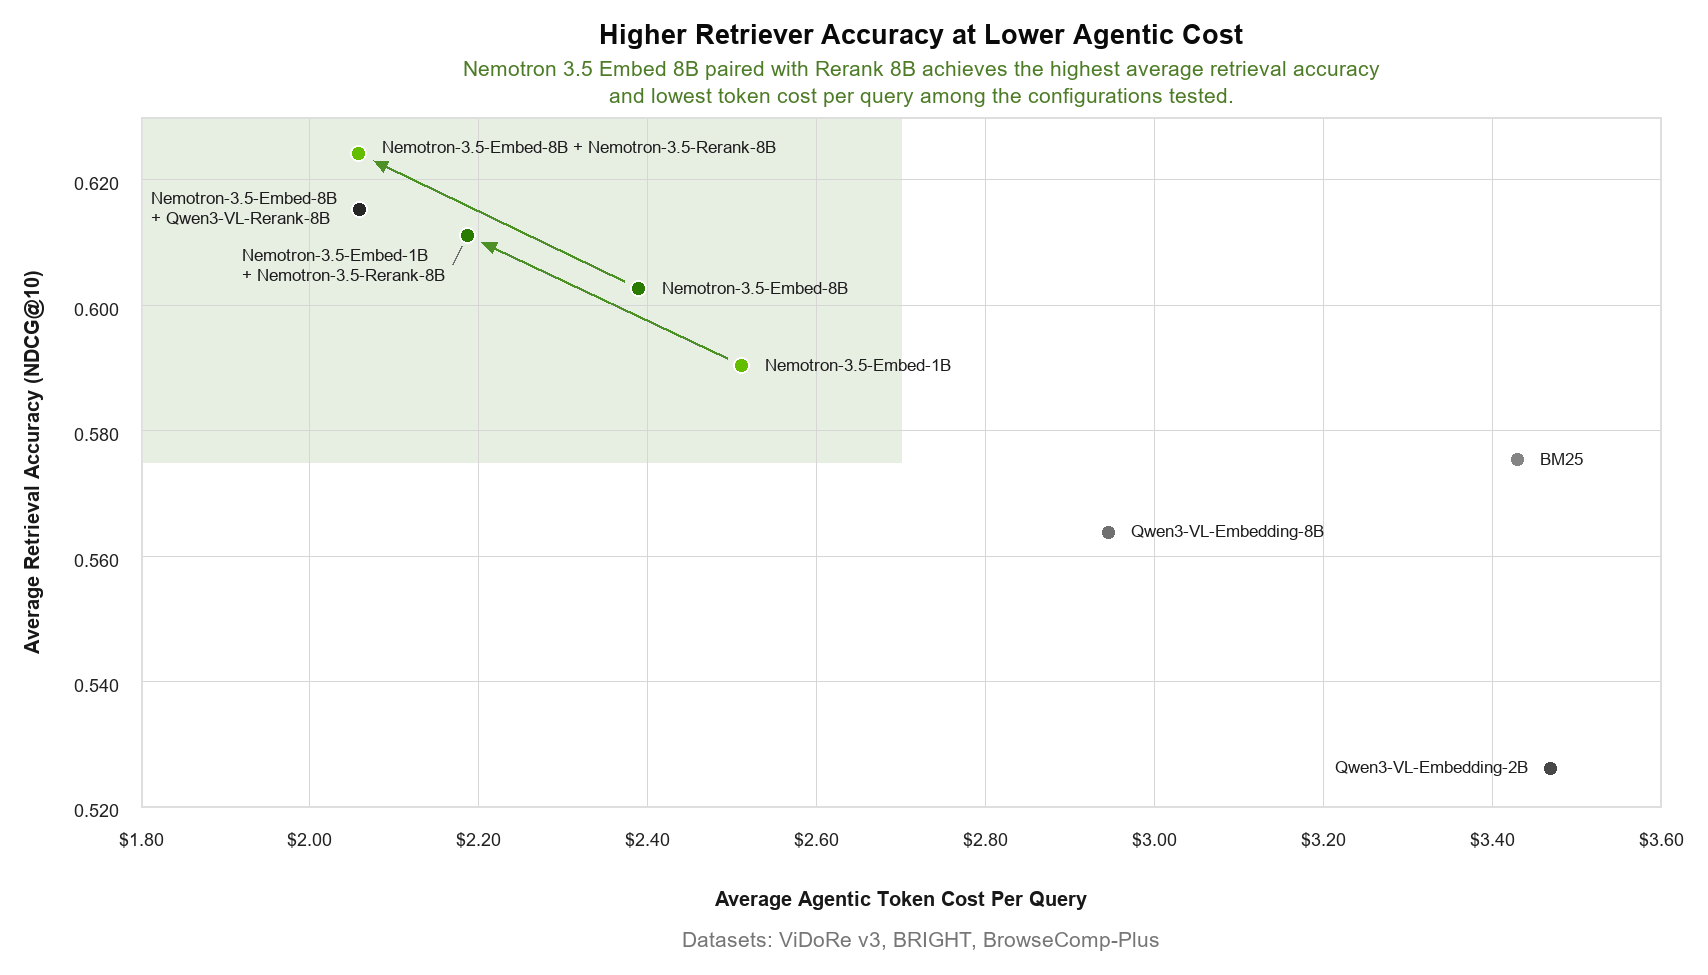
クエリごとのコストを横軸にとったグラフが以下。Nemotron-3.5-Embed-8B-BF16はNemotron-3.5-Rerank-8B-BF16と組み合わせることでコストを削減しつつ精度を向上させられます。
Nemotron-3.5-Parseの精度も競合モデルと比べて高いことがアピールされています。以下のグラフは横軸が秒間処理ページ数、縦軸が精度を示しており、Nemotron-3.5-Parseの処理速度が目立つ結果となっています。
KioskNews shows a cleaned-up reading view extracted from the publisher’s page — the original always lives on their site, not ours.